AI Music Artifacts: What A Cleanup Pass Can And Cannot Fix
Your track came out of the generator with a glassy, metallic top end and drums that click instead of snap, and no amount of re-prompting shifts it. That is not your export settings. AI music artifacts are produced by the generator's own architecture: Deezer's research team traced the tell-tale spectral peaks to the deconvolution modules inside the decoder, and showed that a criterion built on those peaks alone detects AI-generated music with accuracy surpassing 99% in several scenarios. A cleanup pass works on that texture — and on nothing else, which is the half nobody writes down. We read both relevant papers, DistroKid's AI-upload rules, YouTube's Gen AI metadata field and Suno's terms at source on 4 November 2026. Here is what changes at each stage, the three gates a release has to clear, and which one audio processing reaches.
The short version
Four findings, each from a document or a dataset you can open yourself.
The short version: the artifacts are architectural. Deezer's Fourier analysis attributes the spectral peaks in AI music to deconvolution modules in the generator's decoder — the model's architecture, not its training data or weights, validated on Suno and Udio output.
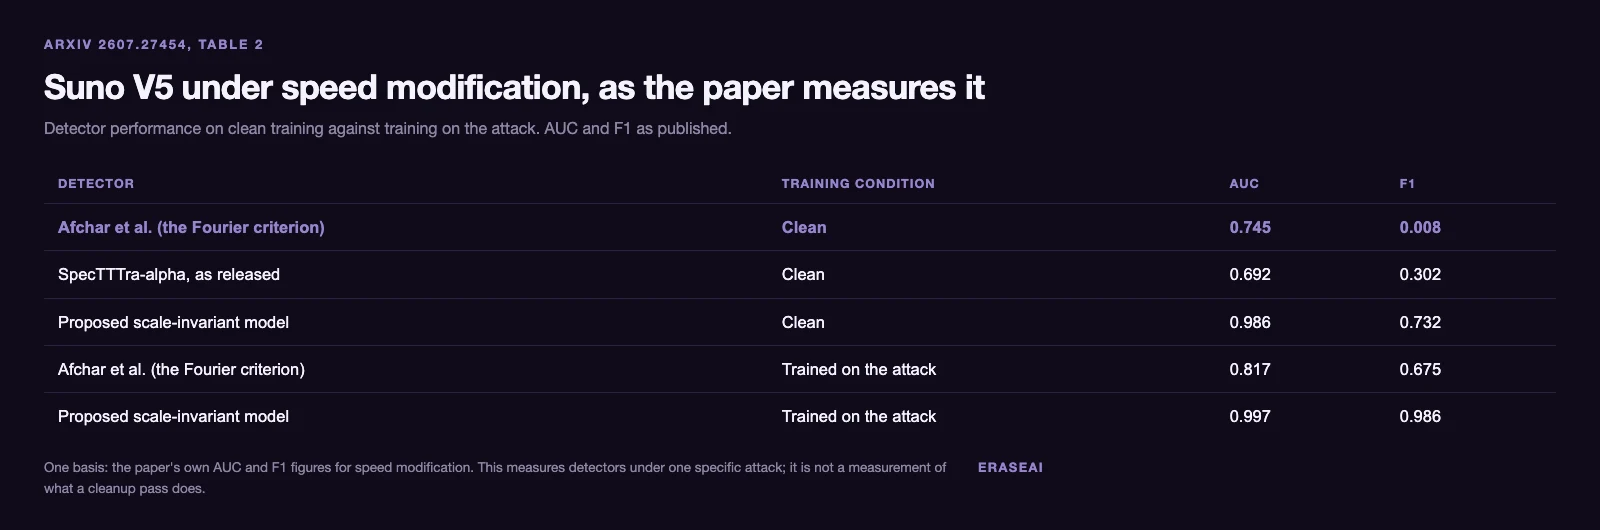
Older detectors fall over on a speed change. On speed-modified Suno v5 the Fourier criterion scores 0.745 AUC and 0.008 F1, while July 2026's scale-invariant model holds 0.986 and reaches 0.997 trained on the attack.
What a cleanup chain does is untested. That paper's limitations say “Other common manipulations (equalization, dynamic range compression, codec compression) remain untested” — nobody has published what EQ and compression do to a detector's score.
Processing reaches one of three gates. DistroKid's four AI conditions are all rights rules, and YouTube's AI designation is a delivered metadata value — all, partly, none or unknown. Only automated screening sees your audio.
- What an AI music artifact actually is
- Why they are built in, not a bad export
- The five stages, and what changes at each
- The three gates every release meets
- What detectors measure, and what nobody has tested
- Cleanup is not mastering, and the order matters
- What a cleanup pass cannot fix
- Running the pass without wrecking the track
- FAQ
- Sources, and what we could not read
What an AI music artifact actually is
Start with what it is not, because the word “artifact” is borrowed from audio repair and brings the wrong mental model with it. In repair work an artifact is damage added to a real recording — hum, clicks, a dropout, tape hiss — and the standard technique is to profile a quiet passage so the tool learns what the noise sounds like alone. A generated track gives you neither: no clean original underneath, and no silent passage to profile, because what you want to remove was never separate from the music. It was produced in the same pass.
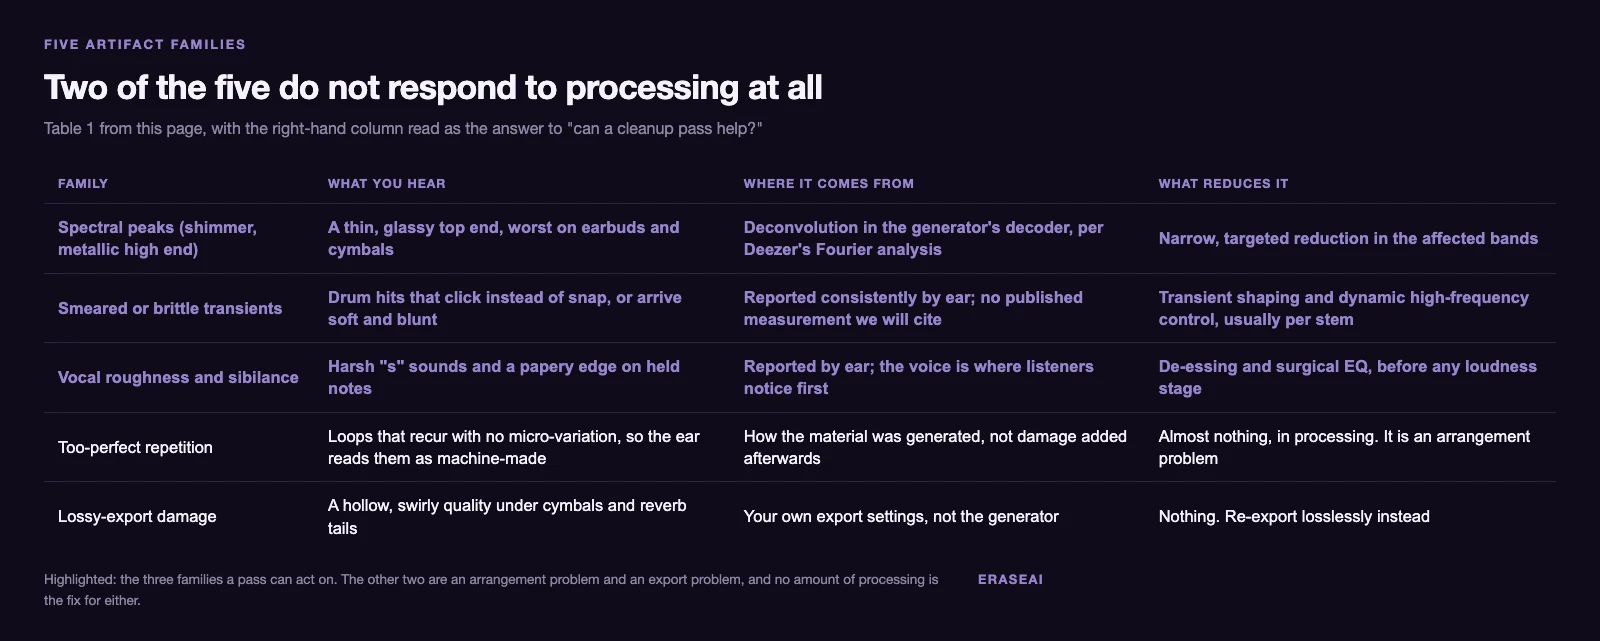
So an AI music artifact is better described as a signature of how the audio was made. The five families below are the ones creators actually complain about, and they do not share a cause: two are properties of the generator, one is an arrangement problem wearing a signal-processing costume, and one is something you did to your own file on the way out. Treating them as one thing is why so many cleanup attempts either do nothing or flatten the track.
| Family | What you hear | Where it comes from | What reduces it |
|---|---|---|---|
| Spectral peaks (“shimmer”, metallic high end) | A thin, glassy top end, worst on earbuds and cymbals | Deconvolution in the generator's decoder, per Deezer's Fourier analysis | Narrow, targeted reduction in the affected bands |
| Smeared or brittle transients | Drum hits that click instead of snap, or arrive soft and blunt | Reported consistently by ear; no published measurement we will cite | Transient shaping and dynamic high-frequency control, usually per stem |
| Too-perfect repetition | Loops that recur with no micro-variation, so the ear reads them as machine-made | How the material was generated, not damage added afterwards | Almost nothing, in processing. It is an arrangement problem |
| Vocal roughness and sibilance | Harsh “s” sounds and a papery edge on held notes | Reported by ear; the voice is where listeners notice first | De-essing and surgical EQ, before any loudness stage |
| Lossy-export damage | A hollow, swirly quality under cymbals and reverb tails | Your own export settings, not the generator | Nothing. Re-export losslessly instead |
Note the third column. Only the first row has a published cause behind it; the rest are consistent listener reports, and we will not invent a mechanism for them — which is the difference between this page and the ones ranking for the subject, several of which assert exact bands and percentages with nothing cited underneath. Our AI audio cleanup guide walks the whole raw export layer by layer.
Why they are built in, not a bad export
The one part of this subject that has a peer-reviewable answer, and no page on the first results page for it cites the paper.
In A Fourier Explanation of AI-music Artifacts, published to arXiv on 23 June 2025, four Deezer researchers — Darius Afchar, Gabriel Meseguer-Brocal, Kamil Akesbi and Romain Hennequin — take the familiar “checkerboard” problem from image generation and run it through audio. Their argument is that the deconvolution modules generative models use to build a waveform up to full resolution leave small but distinctive peaks in the frequency spectrum, and that those peaks are a consequence of the architecture itself rather than of the training data or the learned weights. They validate it on open-source models and then on commercial output from Suno and Udio.
The practical consequence is blunt: you cannot prompt your way out of it, and you cannot export your way out of it. If the peaks come from the shape of the decoder, then the same artifacts arrive on your best generation and your worst, at every bitrate the tool offers, in every genre. The only things that change them are a different decoder design or processing applied afterwards.
Our reading of arXiv:2506.19108, abstract and claims, 4 November 2026
The second consequence is the uncomfortable one: the same paper reports that a simple criterion built on those peaks detects AI-generated music with accuracy surpassing 99% in several scenarios, on par with deep-learning approaches. That is not a classifier guessing from vibes but a measurement of a structural fingerprint — which is why “it sounds human to me” has never been a useful test. Our detector write-up covers the tools built on this, and sunowatermark's pillar on how AI music detectors work goes deeper into the signal side.
The five stages, and what changes at each
Five stages, one signal pass. The fourth column is the one that makes this a flow rather than a black box.
| Stage | What changes | What it cannot change |
|---|---|---|
| 01 Generate | Nothing yet. Export the highest-quality file the tool offers | The artifacts are already in the file at this point |
| 02 Process | The file is analysed and the artifact bands identified | Your rights, your metadata or your disclosure |
| 03 Reduce | Spectral peaks, harsh high end and transient roughness come down | Arrangement, melody, structure, or a repetition problem |
| 04 Review | You decide whether the creative core survived the subtraction | Nothing — this stage is a judgement, not a process |
| 05 Prepare | Hand-off to mastering, then to a distributor | A distributor's rights rules or a platform's AI label |
Two stages do more work than their position suggests. Stage 01 is where most quality is lost and nobody notices, because the decision is made before you are thinking about cleanup: export lossless if the tool offers it. A compressed export has already thrown away detail that stage 03 would otherwise have had to work with, and you cannot get it back by processing harder.
Stage 04 is not a formality either. Subtraction has a point past which the track stops sounding like itself, and you have traded one artificial quality for another. Compare the two files at matched loudness, because the louder of two almost always sounds better for reasons that have nothing to do with the cleanup. And what no stage in that table touches is the paperwork — which is where most rejections actually happen.
The three gates every release meets
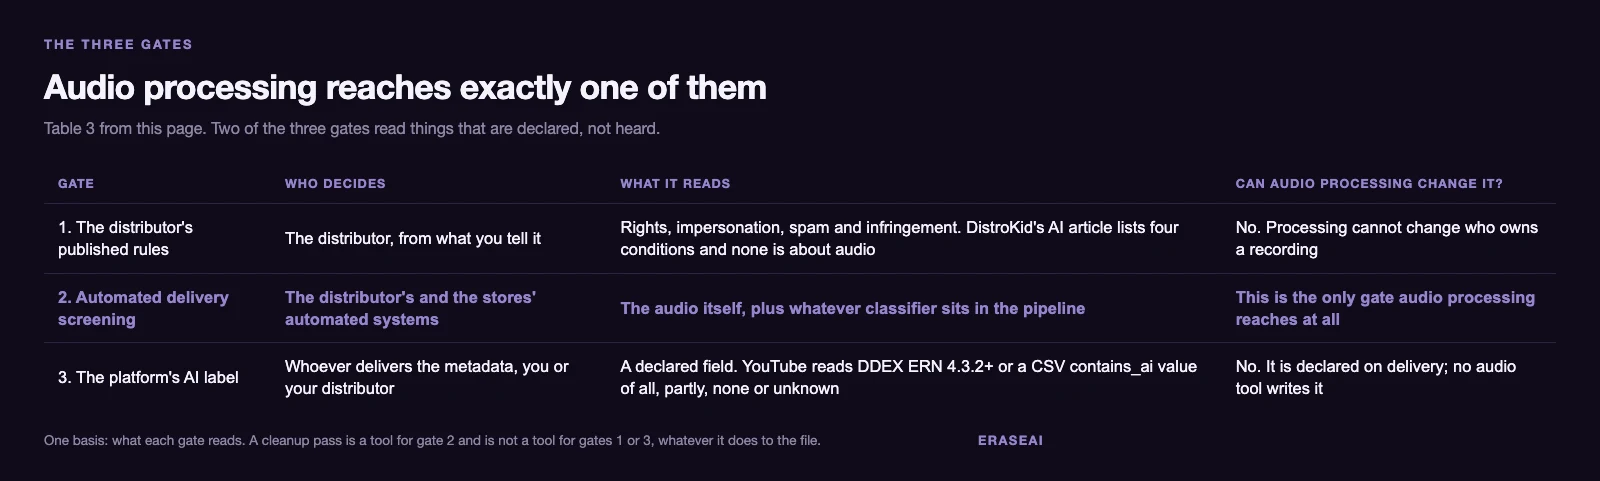
Conflating these three is the single most expensive mistake in this niche, and it is the reason people buy processing expecting it to do something it cannot.
| Gate | Who decides | What it reads | Can audio processing change it? |
|---|---|---|---|
| 1. The distributor's published rules | The distributor, from what you tell it | Rights, impersonation, spam and infringement. DistroKid's AI article lists four conditions and none is about audio | No. Processing cannot change who owns a recording |
| 2. Automated delivery screening | The distributor's and the stores' automated systems | The audio itself, plus whatever classifier sits in the pipeline | This is the only gate audio processing reaches at all |
| 3. The platform's AI label | Whoever delivers the metadata — you, or your distributor | A declared field — YouTube reads DDEX ERN 4.3.2+ or a CSV “contains_ai” value of all, partly, none or unknown | No. It is declared on delivery; no audio tool writes it |
Gate 1 is published and it is not about sound. DistroKid's help article on AI uploads, last updated 19 August 2026, opens “Yes—DistroKid accepts music created with AI tools, but there are some rules” and gives four: own 100% of the rights, no impersonation of a voice or likeness, no mass-generated spam, no infringement. Notice what is absent — no audio-quality condition anywhere in the list — and that it closes by noting streaming services may still reject or remove a release that fails their own guidelines. Nor is DistroKid an outlier: several distributors accept AI music openly, which we map on platforms that accept AI music.
Gate 3 is the one worth being precise about, because it is where most of the marketing in this category is quietly dishonest. A platform's AI label is a declared field, not a measurement of your file. YouTube's partner documentation sets out how: Gen AI information is delivered through DDEX ERN 4.3.2+ or a CSV template, and the contains_ai column takes one of four values — “all”, “partly”, “none”, or “unknown” to reset a value declared wrongly before. Deliver nothing and YouTube reads it as unknown unless it can determine otherwise from its own signals, in which case it may designate the content fully or partly Gen AI itself.
So no audio tool — ours, anyone's — changes how a platform labels your release: the label is typed into a delivery field by you or your distributor. Processing acts on gate 2 and the texture underneath it. The practical version of the declaration side is on disclosure that works.
What detectors measure, and what nobody has tested
The most recent robustness paper is three months old, and its limitations section is more useful to you than its results.
Improved Robustness in AI-Generated Music Detection (arXiv 2607.27454, submitted 29 July 2026, revised on the 31st) starts from the awkward fact that detectors which are near-perfect on raw output degrade sharply once the audio has been altered — and the alteration it studies is a change of speed or pitch, which moves every one of those spectral peaks along the frequency axis. Its own detector is invariant to frequency scaling, trained on speed factors from ×0.7 to ×1.4.
| Detector | Training condition | AUC | F1 |
|---|---|---|---|
| Afchar et al. (the Fourier criterion) | Clean | 0.745 | 0.008 |
| SpecTTTra-α, as released | Clean | 0.692 | 0.302 |
| Proposed scale-invariant model | Clean | 0.986 | 0.732 |
| Afchar et al. (the Fourier criterion) | Trained on the attack | 0.817 | 0.675 |
| Proposed scale-invariant model | Trained on the attack | 0.997 | 0.986 |
The 0.008 F1 in the first row is not a typo, and it is the most instructive number here: a detector that is excellent on untouched audio can be reduced to almost no useful positive detections by a transform you could apply in any editor. Note what closes the gap — the two “trained on the attack” rows. Detection is an arms race with a short cycle, so a figure measured in 2025 tells you little about the model running in 2026.
“Other common manipulations (equalization, dynamic range compression, codec compression) remain untested”.
arXiv:2607.27454, Limitations, read at source 4 November 2026
That sentence describes almost everything a cleanup and mastering chain does. The literature has measured a speed change, which no sane release workflow applies, and has not measured EQ, dynamic-range compression or codec compression, which every release workflow applies. The training set was also limited to three generators — Suno v3.5, v5 and Udio v120.
Which is why you will not find a number on this page for how much any processing moves any detector's score. Nobody has published one, our own release-side testing is described on the Undetectr review rather than smuggled in here as physics, and a page quoting a precise percentage for an unmeasured transform is quoting itself.
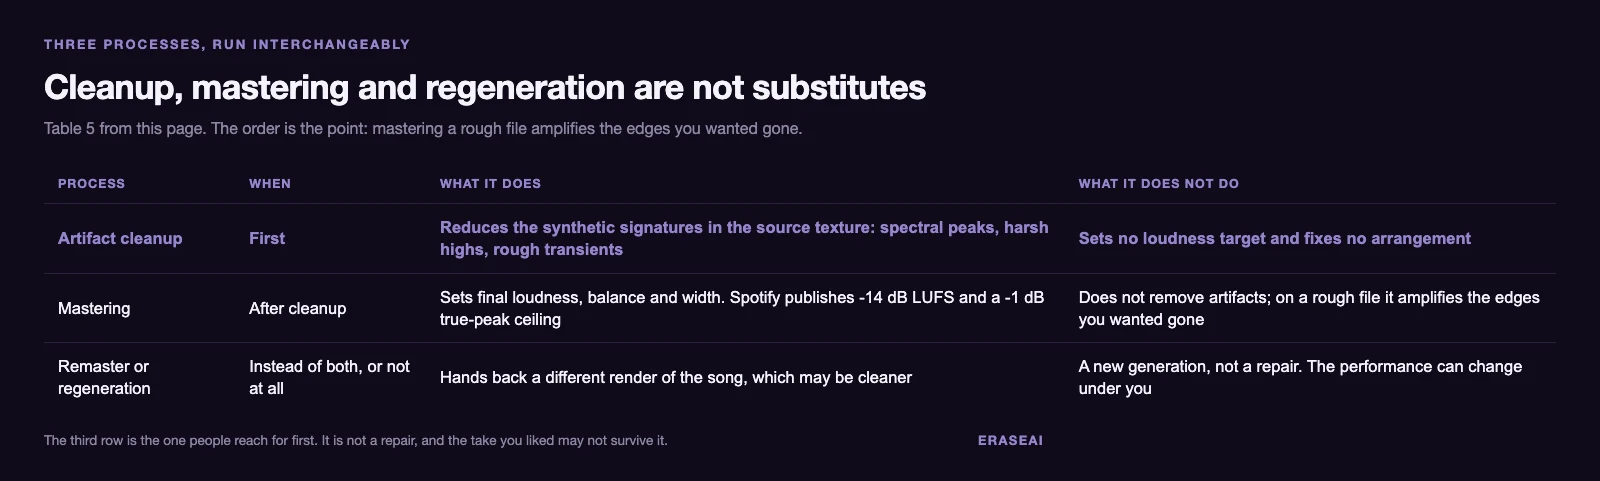
Cleanup is not mastering, and the order matters
| Process | When | What it does | What it does not do |
|---|---|---|---|
| Artifact cleanup | First | Reduces the synthetic signatures in the source texture — spectral peaks, harsh highs, rough transients | Sets no loudness target and fixes no arrangement |
| Mastering | After cleanup | Sets final loudness, balance and width. Spotify publishes −14 dB LUFS and a −1 dB true-peak ceiling | Does not remove artifacts; on a rough file it amplifies the edges you wanted gone |
| Remaster or regeneration | Instead of both, or not at all | Hands back a different render of the song, which may be cleaner | A new generation, not a repair — the performance can change under you |
Run them in that order. Mastering is a loudness and balance stage, so pointing it at a file with harsh spectral peaks raises those peaks along with everything else — the limiter does not know which part of the top end you wanted and which part the decoder left behind. Cleanup first gives mastering a better starting point; it does not replace it. And be careful whose target you are using: Spotify is the one major platform that publishes a loudness figure at all, and the per-platform tables you see everywhere else are third-party measurement presented as specification, which we go into on Suno mastering.
The third row catches people out. A remaster is not a repair pass — it hands you a different render, and the performance you liked can change underneath you. If the vocal take was why you kept the track, that is a real risk rather than a footnote, and our route comparison puts numbers on what each option costs you.
What a cleanup pass cannot fix
A weak arrangement. The too-perfect repetition in Table 1 is the clearest case. No processor has an opinion about whether your second chorus should differ from your first, and a loop reads as machine-made because nothing in it moves. That is fixed by editing, re-generating a section, or playing something over the top — not by a signal pass.
Detail that was never there. Subtraction cannot restore information. If the generator did not produce a convincing cymbal, cleanup gives you a quieter unconvincing cymbal. The same applies to anything a lossy export discarded on the way out, which is why the last row of Table 1 reads “nothing”.
Marks a generator deliberately appended. A different layer, with different rules. Suno's terms of service, revised 10 August 2026 and effective 3 September 2026, state that you agree not to “remove, alter, obscure or circumvent any fingerprint, watermark or metadata Suno appends to an Output”, and that obtaining a copy of an Output other than through a download channel Suno makes available is prohibited. An artifact pass works on the audible texture the decoder leaves behind as a by-product of generation — not the same object as a mark somebody added on purpose, and a distinction to keep straight before reaching for any tool. The identifier layer is covered on the watermark page.
A platform's AI label, and the audience problem. Gate 3 is declared, so nothing in the signal reaches it. And the honest closing caveat is bigger than all of this: what most AI releases are short of is not cleanliness or distribution, it is listeners. A clean file clears a step. It does not find you an audience, and anyone implying otherwise is selling you something.
Running the pass without wrecking the track
Keep the original, always. Process a copy. This sounds obvious until the third pass, when you have lost track of which file still had life in it — and a generator's output is not always reproducible later.
One pass, not a stack. The instinct when something still sounds synthetic is to add a second cleanup stage, then a third; the result is a dull file with the same repetition problem. If one targeted pass has not fixed it, the problem is in a row of Table 1 cleanup does not own.
Work per stem where you can. A broad high-shelf cut that tames a metallic hi-hat also takes the air off the vocal. Where stems exist the narrow fix beats the wide one; where they do not, dynamic processing that acts only when the harshness appears beats a static cut that is always on.
Then the release steps, in order. Clean, master, check the rights conditions at gate 1, declare accurately at gate 3, submit. For the artifact and screening part — the step this site exists for — Undetectr is the pass we point creators at, and the button below goes straight to it. It works on the texture and the screening step, and has no effect whatsoever on how a platform labels your release.
And when the file is finished, the next wall is the one in the section above. Streaming discovery is closed enough that a storefront and a sync route are worth more to most people than another upload: paid placements in TV, film, games and ads are where the money talk in this niche actually is, and played.fm's sync route is built for pitching into them, with selling direct to your own listeners beside it. Worth noting the contrast, too: Bandcamp bars music generated wholly or substantially by AI, so “just sell it on Bandcamp” is not available to this catalogue.
Ready to run the cleanup pass?
Move your AI track through a pass built for generation artifacts and delivery screening — not for changing any platform's AI label, which no audio tool can do.
▸ Independent · We recommend Undetectr
AI music artifacts FAQ
What causes AI music artifacts?
For the metallic, shimmery high end, Deezer's researchers trace it to deconvolution modules inside the generator's decoder — architecture, not training data or weights, validated on Suno and Udio output. That is why a better prompt or a cleaner export does not remove it. Other complaints, such as blunt transients, are reported consistently by listeners with no published cause we will cite.
Can you remove AI artifacts completely?
No. A cleanup pass is subtraction: it lowers energy in the bands where the artifacts live and softens rough transients. It cannot restore detail the generator never produced, and it cannot reach a repetition problem, which is arrangement rather than signal.
Does cleaning a track stop it being detected as AI?
Nobody can honestly tell you by how much, because the published literature has not measured it. July 2026's robustness paper tested speed and pitch changes and says in its limitations that equalization, dynamic range compression and codec compression “remain untested” — precisely what a cleanup and mastering chain performs.
Does a cleanup pass remove Suno's watermark?
That is a different layer with different rules. Suno's terms of service, effective 3 September 2026, say you agree not to “remove, alter, obscure or circumvent any fingerprint, watermark or metadata Suno appends to an Output”. An artifact pass targets the audible texture the decoder leaves behind as a by-product of generation.
Will a distributor reject my track because of artifacts?
Not for the artifacts as such. DistroKid's AI article accepts music made with AI tools on four conditions — rights, impersonation, spam, infringement — and none of them is an audio-quality rule. What creators do report is automated screening flagging and rejecting individual releases.
Does exporting at a higher quality reduce artifacts?
It does not reduce the ones the generator created, because those are in the audio before you pick a format. It does stop you adding a second, avoidable layer: a lossy export discards detail a later cleanup stage would have worked with.
Sources, and what we could not read
- A Fourier Explanation of AI-music Artifacts — Afchar, Meseguer-Brocal, Akesbi and Hennequin, arXiv:2506.19108, 23 June 2025. The deconvolution account of the spectral peaks, the architecture-not-weights claim, validation on Suno and Udio, and the detection criterion surpassing 99% accuracy in several scenarios.
- Improved Robustness in AI-Generated Music Detection — Dugelay, Barand, Laouar, Campeas, Afchar and Hennequin, arXiv:2607.27454, 29–31 July 2026. Table 4 above is its Table 2, read in the full HTML version, along with the ×0.7–×1.4 speed range, the three generators used, and the limitations sentence quoted verbatim.
- DistroKid, Can I Upload Music Made With AI Tools to DistroKid? — help article 41182362733715, last updated 19 August 2026, for the opening sentence and the four conditions.
- YouTube Help, Gen AI disclosures for music partners — for DDEX ERN 4.3.2+, the four
contains_aivalues, the Fully / Partly / No Gen AI designations, and the rule that an omitted value is read as unknown unless YouTube determines otherwise from its own signals. - Spotify for Artists, loudness normalization for −14 dB LUFS, the −1 dB true-peak advice and the three listener presets, and Suno's terms of service (revised 10 August 2026, effective 3 September 2026) for the fingerprint-and-watermark clause and the download-channel clause.
- What we could not read. DistroKid's help centre returns 403 to a plain request from our environment, so that article was read through its public JSON endpoint, which serves the same body and update date. One ranking page, ceek.com's “Behind the Glitch”, now 404s and is named unread rather than summarised. We ran no audio tests for this page: every figure above is someone else's published number, with a link to it.
Detection research on this subject is moving in months, not years, so treat Table 4 as a snapshot of July 2026 rather than a standing result. Sources read at origin 4 November 2026. Last updated 4 November 2026.
Related guides
AI audio cleanup, layer by layer
The four layers in a raw export, and the order to clear them in.
AI music artifact remover
Four routes compared on what each one costs you.
Suno mastering
Why remaster is not mastering, and the only published loudness target.
Do AI music detectors work?
What the tools built on these spectral peaks actually score.
Platforms that accept AI music
Every published distributor position, read at source and dated.
AI music disclosure that works
The declaration fields that exist, and what each one does.
Or browse every guide on the site.